|
Ruirong Feng I am a second-year master’s student at Princeton University, where I work with Prof. Jianqing Fan on causal inference and transfer learning, and with Prof. Chi Jin on LLM post-training and recursive self-improving. I received my bachelor’s degree with distinction from Peking University in 2025. My research lies at the intersection of statistics and machine learning, with a focus on generalization, adaptation, and learning from feedback. On the statistical side, I study causal inference and transfer learning, with a focus on reliable causal effect estimation across populations and environments. On the machine learning side, I am interested in reinforcement learning and LLM agents, especially how agents can learn and improve through interaction and feedback. My broader interests include causal representation learning and multi-agent collaboration. I am currently seeking Ph.D. opportunities starting in Fall 2027. Also feel free to reach out if you want to chat about research or collaborations! |
|
News
|
Research(* indicates equal contribution, (α-β) indicates alphabetical order) |
|
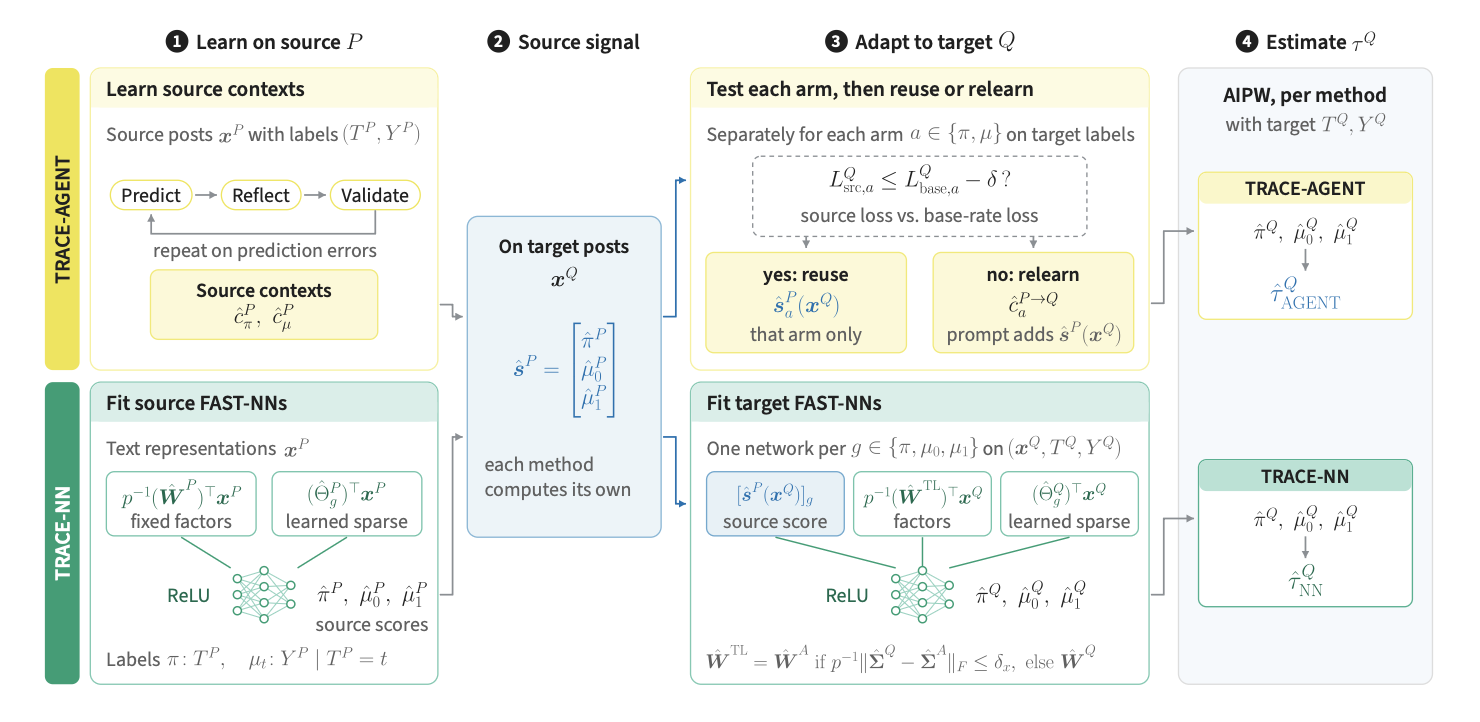
TRACE: Benchmarking Agentic Causal Estimation from Text under Covariate and Posterior Shift
Jianqing Fan, Ruirong Feng, Qishuo Yin (α-β) Under Review, 2026 arXiv (coming soon) A benchmark for estimating causal effects from text when the target population differs from the source, with an LLM-agent method (TRACE-Agent) and a neural-network method (TRACE-NN) that transfer what they learn on the source to the target. |
|
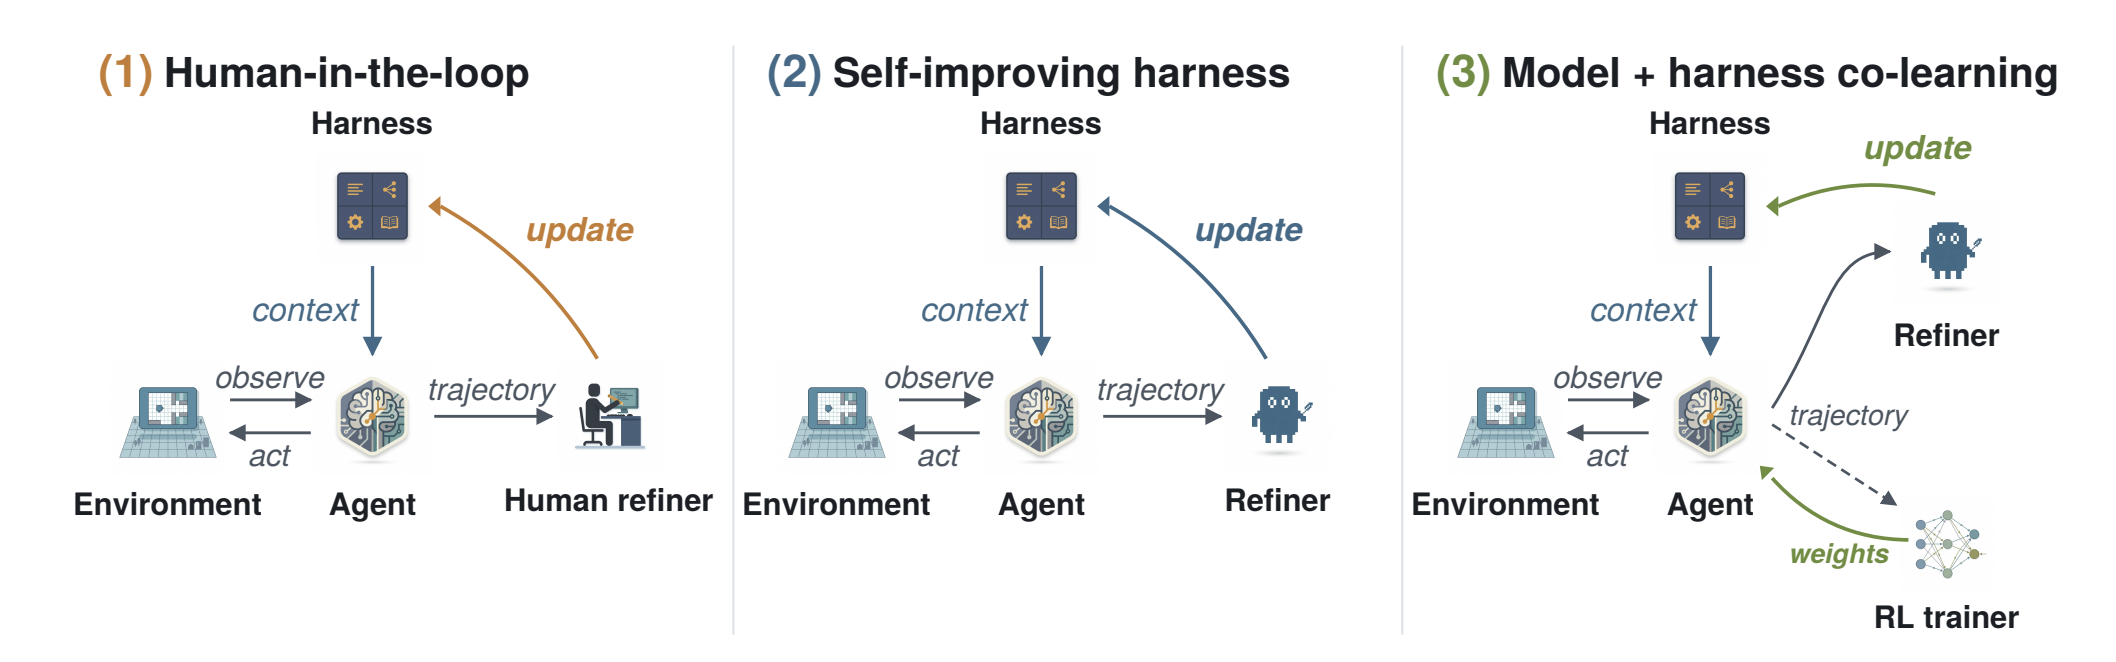
Continual Harness: Online Adaptation for Self-Improving Foundation Agents
Seth Karten*, Joel Zhang*, Tersoo Upaa Jr*, Ruirong Feng, Wenzhe Li, Chengshuai Shi, Chi Jin, Kiran Vodrahalli arXiv, 2026 project page / code / arXiv A reset-free, self-improving harness for embodied agents: the agent alternates between acting and refining its own prompt, sub-agents, skills, and memory within a single run, without human intervention. |
|
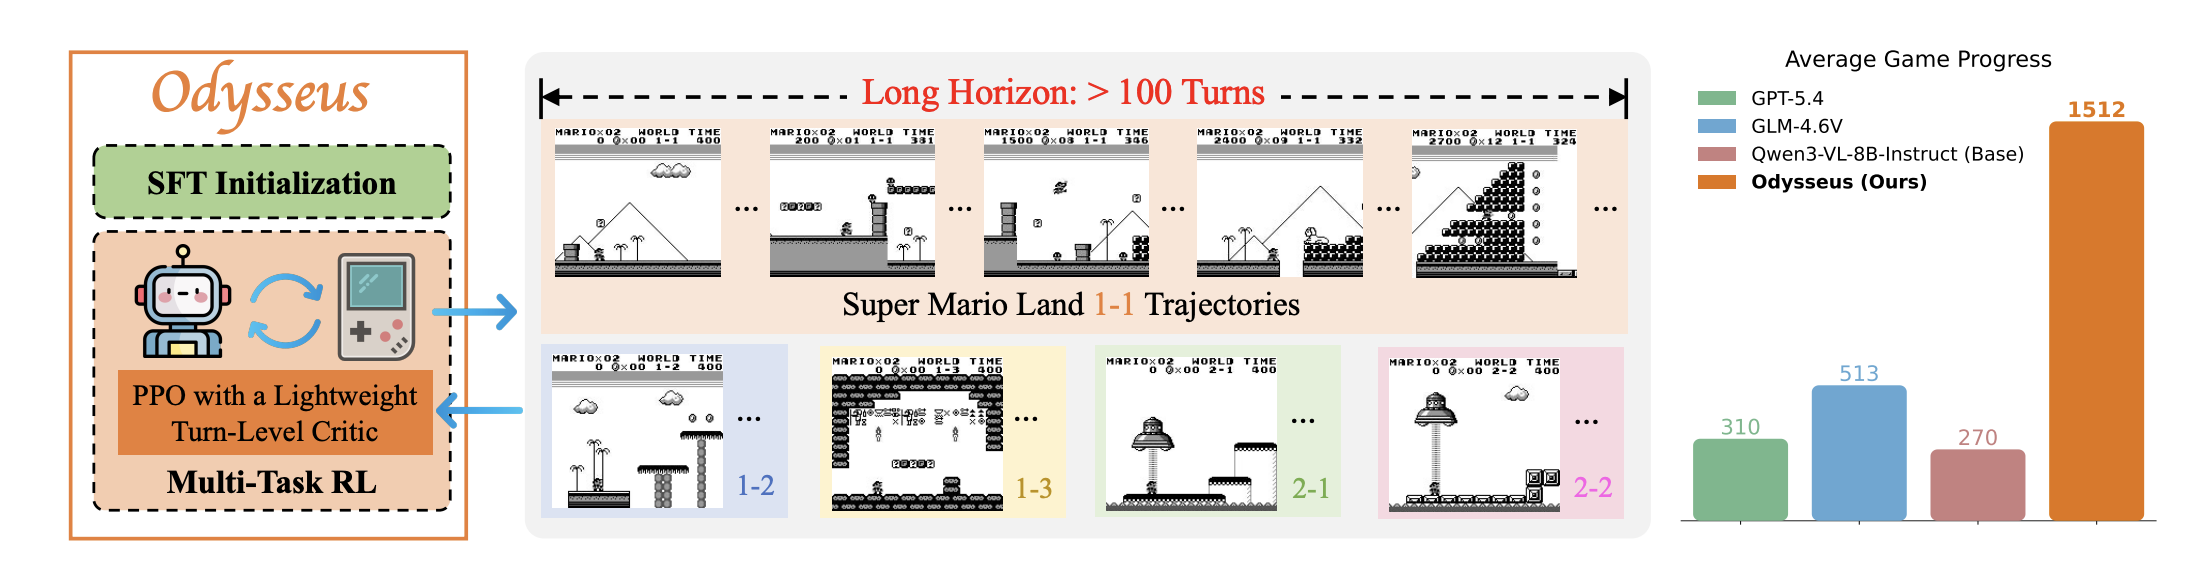
Odysseus: Scaling VLMs to 100+ Turn Decision-Making in Games via Reinforcement Learning
Chengshuai Shi, Wenzhe Li, Xinran Liang, Yizhou Lu, Wenjia Yang, Ruirong Feng, Seth Karten, Ziran Yang, Zihan Ding, Gabriel Sarch, Danqi Chen, Karthik Narasimhan, Chi Jin COLM, 2026 project page / arXiv An RL framework (PPO with a lightweight turn-level critic) that trains VLMs to play Super Mario Land over 100+ turns, reaching at least 3× the average game progress of frontier models. |
Blogs |
|
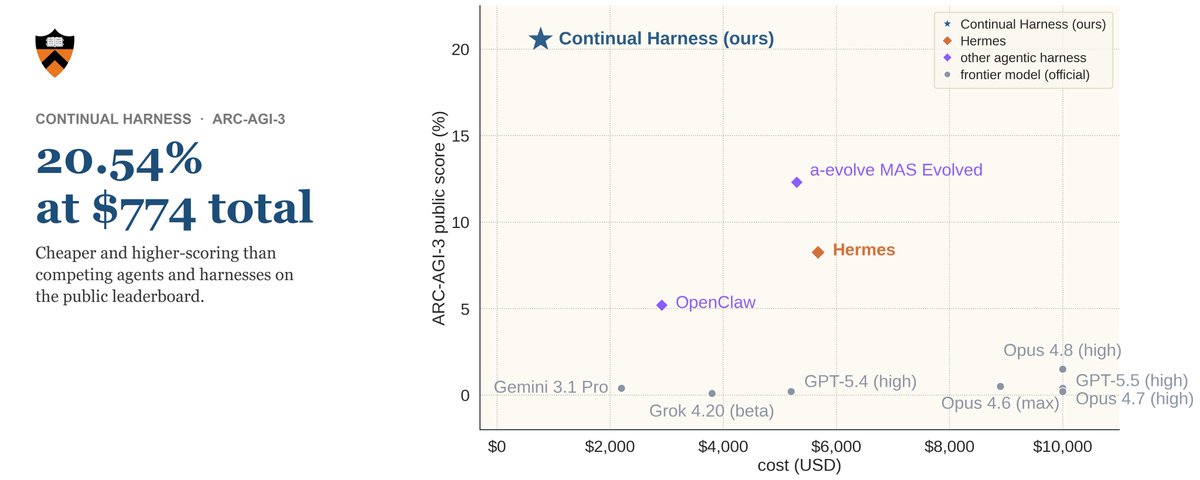
Continual Harness: An Efficient Self-Improving Agent on ARC-AGI-3
Ruirong Feng, Seth Karten, Wenzhe Li, Chengshuai Shi, Chi Jin Blog post, 2026 blog / code / scorecard / paper Continual Harness scores 20.54% on the ARC-AGI-3 public set at a total cost of only $774, outperforming other agentic harnesses on the leaderboard at a fraction of their cost. Its efficiency comes from reusing saved skills (62% of executed actions) and from reset-free refinement that turns early exploration into an editable world model for later levels. |
Teaching
|
|
Website template from Jon Barron. |